

Hi all, we start with some rumors and then look at some updates from the Chinese big tech behemoths.
Rumors: DeepSeek R2 Leak Reveals Cost Efficiency and Performance Metrics
Over the past weekend, news of an R2 leak has circulated on X and Chinese social media. The R2 model was reportedly scheduled for release in early May, but that may now be accelerated. According to SCMP’s report, Chinese stock-trading social-media platform Jiuyangongshe wrote that R2 is developed with a so-called hybrid mixture-of-experts (MoE) architecture, with a total of 1.2 trillion parameters, making it 97.3 per cent cheaper to build than OpenAI’s GPT-4o.
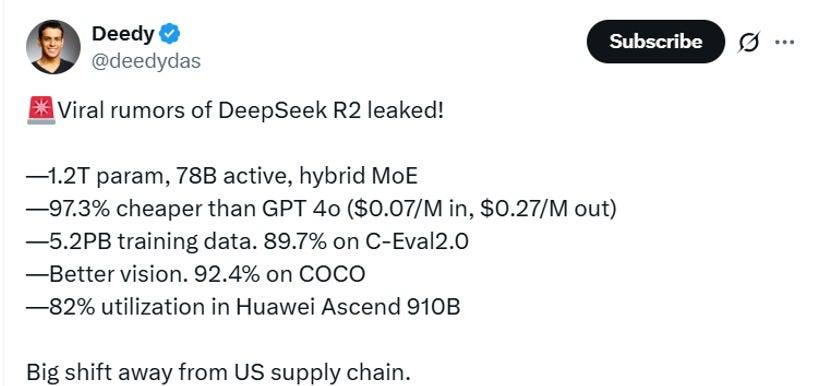
I would still approach this news with caution, as we’re not sure how reliable these online rumors are. But so far, the consistency of details across multiple tech media (including SCMP, I linked to) and the timing of the leaks (ahead of a likely early May launch) have fueled expectations.
Key Rumored Features (Reddit)
Massive Scale:
DeepSeek R2 is said to feature a 1.2 trillion parameter architecture, with 78 billion parameters active per token, leveraging a hybrid Mixture-of-Experts (MoE) design. This approach allows for high performance while keeping computational costs low.Cost Efficiency:
The most widely cited rumor is that R2 is 97.3% cheaper to train and run than OpenAI's GPT-4 or GPT-4o. API pricing is rumored at $0.07 per million input tokens and $0.27 per million output tokens. This would make R2 dramatically more affordable for enterprise and developer use.Hardware Independence:
Unlike most leading AI models, DeepSeek R2 is reportedly trained entirely on Huawei's Ascend 910B AI chips, not Nvidia hardware. This marks a strategic shift, signaling China's growing self-sufficiency in AI infrastructure. Reports claim DeepSeek achieved 82% utilization of its Huawei GPU cluster, reaching 512 PetaFLOPS of FP16 compute.Training Data and Benchmarks:
R2 is rumored to have been trained on 5.2 petabytes of high-quality data, spanning domains like finance, law, and patents. Early leaks suggest it scores 89.7% on C-Eval 2.0 (a Chinese language benchmark) and 92.4% on the COCO vision benchmark, indicating strong reasoning and multimodal (text + vision) capabilities.Multimodal Capabilities:
Multiple sources speculate that R2 will natively support both text and vision tasks, which is in line with the latest trends in state-of-the-art AI models. This would be a major step up from DeepSeek's previous text-only releases.Open-Source Release:
DeepSeek is expected to continue its open-source strategy, potentially making R2 freely available and further challenging established players like Meta and OpenAI in the developer ecosystem.
The leak also noted what we’ve predicted: a Nvidia H20 ban will matter much less to Chinese LLM development now as they shift away from the U.S. supply chain and to domestically made chips. [See Fortune op-ed U.S. tariffs will hasten, not slow, China’s drive for tech self-sufficiency]
Ok, China's leading technology firms, Alibaba, and Baidu, are actively advancing their artificial intelligence capabilities. Over the past week, they’ve both rolled out new models and are exploring various applications and monetization strategies. These developments coincide with observations regarding China's Internet valuation closing the gap with U.S. peers.
Baidu's Strategic AI Roadmap and Monetization Efforts
Baidu launched a new AI model, Ernie 4.5 Turbo. At the Baidu Create 2025 event, the tech giant announced two new models, ERNIE 4.5 Turbo and X1 Turbo, which are described as enhancing multi-modal and deep reasoning capabilities at low cost.
The event also saw the introduction of several multi-modal and multi-agent applications. Baidu emphasized the importance of MCP (Model Context Protocol), positioning it as an industry standard addressing developers' pain points.
Baidu has outlined its AI strategy and recent achievements, highlighting both short- and long-term opportunities in AI, including digital humans, coding agents, and autonomous driving. Chatbots are noted as still evolving, currently showing low engagement.
The company’s short- and long-term priority in AI development remains in lowering training and inference costs of large models, creating opportunities in digital humans (streaming/customer service) and coding agents (facilitating AI agent development).
Although it’s been leading in autonomous driving, many competitors in China are catching up, and the next phase of focus will be achieving AGI, but that is expected to take over 10 years. Its robotaxi (RT-6) is deemed highly competitive and cost-effective compared to many overseas peers. So there’s more to anticipate in this space.
Frankly speaking, Baidu’s 2C chatbot and offerings have lagged behind competitors and have not offered any major breakthrough or anything exciting in a while.
Alibaba Debuts Qwen3 with Enhanced Performance
Alibaba has introduced Qwen3 on Tuesday, described as setting a new benchmark for open-source AI. It is based on a hybrid reasoning model. Nathan Lambert wrote a very insightful and technical piece here.
Just to highlight a few key points from the Qwen3 debut:
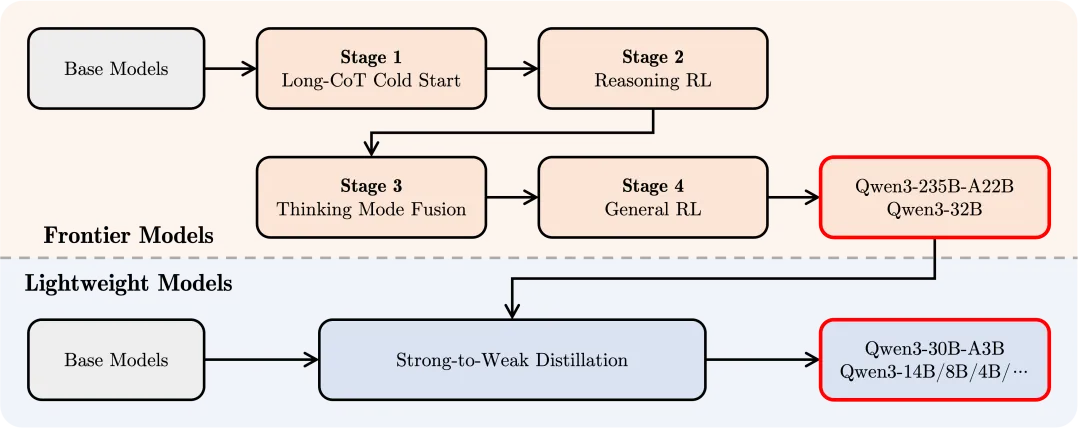
Hybrid Reasoning Model: Uses a 4-stage training process .
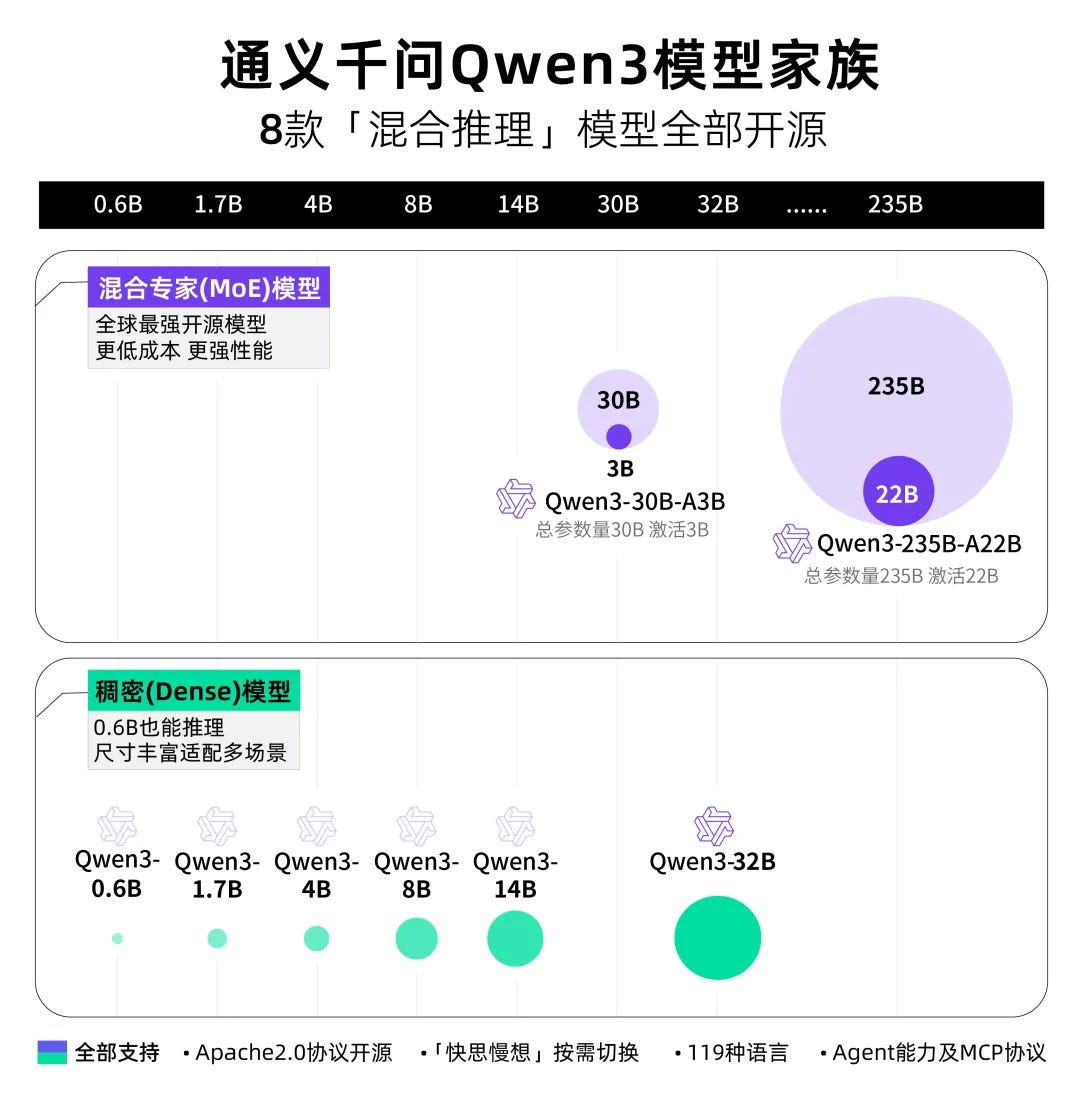
Model Architecture: Released six dense models (0.5B, 1.8B, 4B, 14B, 32B parameters) and 2 MoE models (30B with 3B active and 235B with 22B active).
Training Data: Qwen3 is trained on 36 trillion tokens, double the number used for Qwen2.5 .
Enhancements: Key enhancements in multilingual tasks, stronger agent integration, superior reasoning, and human alignment.
Performance: Achieved top results in different areas, and performance comparable with other top-tier models.
The hybrid reasoning model allows users to switch between thinking modes for complex, multi-step tasks such as mathematics, coding, logical deduction, and a non-thinking mode for fast, general-purpose responses is available for global users to download. This is achieved via the 4-stage training process, incorporating long chain-of-thought (COT), cold start, reinforcement learning, thinking mode fusion, and general RL.
Alibaba also highlighted that it lowered deployment costs for developers using Qwen3. The Qwen3-235B+22B model is mentioned explicitly as having significantly lower deployment costs compared to other state-of-the-art models.
Comparing Qwen3 to its predecessor, Qwen2.5, the new model demonstrates superior reasoning capabilities. Qwen3's capabilities across benchmarks such as AIMEMaths (mathematical reasoning), LiveCodeBench (coding proficiency), BFCL (tool and function calling), and Arena-hard (instruction-tuned LLM) are described as comparable to other top models, including DeepSeek-R1, o1, o3-mini, Grok-3, and Gemini-2.5-Pro.
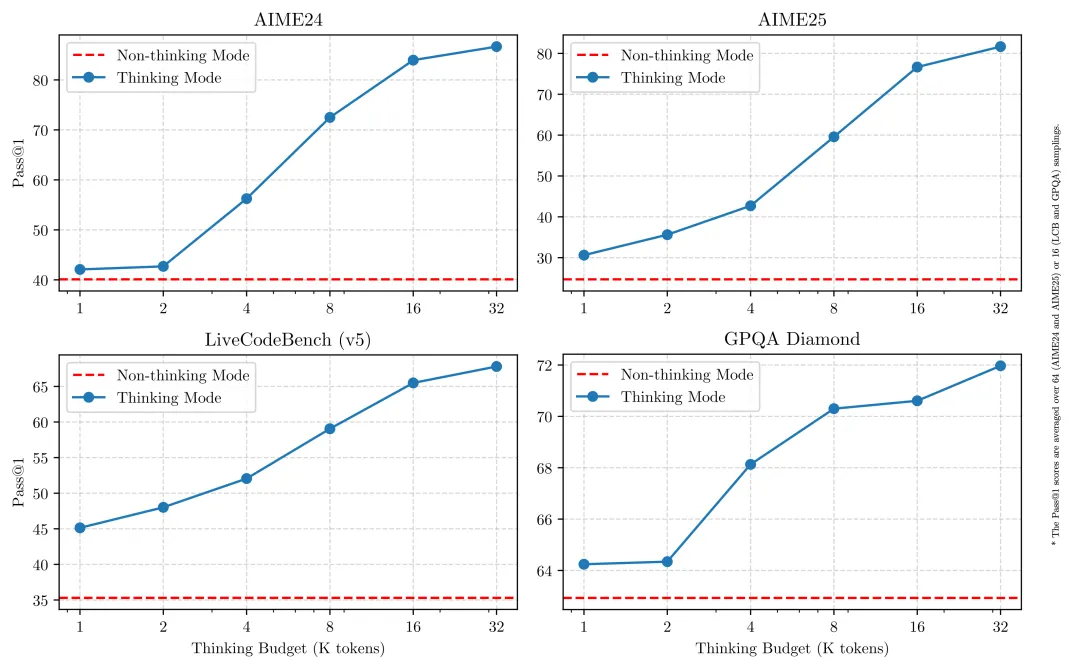
GitHub:https://github.com/QwenLM/Qwen3Hugging Face:https://huggingface.co/collections/Qwen/qwen3-67dd247413f0e2e4f653967fOn the Alibaba Cloud site, the company wrote: “Qwen3 represents a significant milestone on our journey towards Artificial General Intelligence (AGI) and Artificial Superintelligence (ASI). By scaling up pretraining and reinforcement learning, we have achieved a higher level of intelligence. We have seamlessly integrated thinking and non-thinking modes, providing users with the ability to flexibly control their thinking budget. In addition, we have expanded support for multiple languages, helping more users around the world.
Looking ahead, we plan to enhance our model from multiple dimensions. This includes optimizing model architecture and training methods to achieve several key goals: expanding the scale of data, increasing model size, extending context length, broadening the range of modalities, and leveraging environmental feedback to advance reinforcement learning for long-term reasoning. We believe that we are transitioning from an era focused on training models to one centered on training Agents. Our next generation of iterations will bring meaningful progress to everyone's work and life.“
This is a pretty big deal as it reinforced Alibaba’s position as a leading player in China’s AI space with the advantage of also having infrastructure support and distribution reach.
Ray Wang said to CNBC today, “Alibaba’s release of the Qwen 3 series further underscores the strong capabilities of Chinese labs to develop highly competitive, innovative, and open-source models, despite mounting pressure from tightened U.S. export controls.” Adding that, “in the broader context of the U.S.-China AI race, the gap between American and Chinese labs has narrowed—likely to a few months, and some might argue, even to just weeks.”
“With the latest release of Qwen 3 and the upcoming launch of DeepSeek’s R2, this gap is unlikely to widen—and may even continue to shrink,” said the Washington, DC-based semi/ tech analyst.
Conclusion
As written in my Fortune op-ed, “the U.S. may hope that the right mix of tariffs, subsidies, and export controls can preserve its tech leadership. But instead, the continued push to cut off China’s access to advanced technology is going to make it more self-sufficient out of necessity. The trade war, even if it leads to a deal, will push China to invest in its tech sector even more. The next time the U.S. tries something like the H20 chip ban, it may mean very little to the Chinese AI ecosystem.
Competition can be healthy, but it doesn’t need to mean collapse. The challenge for both the U.S. and China is to draw clear guardrails to support national security without shutting down collaboration entirely. Climate tech, healthcare, AI safety, academic research, and open-source development should still be seen as areas for cooperative leadership.”
On top of that, Jefferies wrote in a research note that China’s internet valuation has narrowed the gap with U.S. peers in recent months. And I think that could partly be due to some volatile adjustments for the Mag 7 in the U.S. we saw over the last few weeks and a reinstated confidence in China’s tech sector boosted by DeepSeek.
Jefferies added that, recent earnings results for most large and mid-cap companies across sub-sectors were either in line with or beat expectations, setting a solid foundation for expected growth. Things are catching up and China’s AI space seems to be getting more and more self-reliant.
Ok guys, I’ll (try to) be offline for a week. Taking my little one to Japan for some major yumz and nomz.
Cool